Database hot spots explained: why one shard is on fire
You split your database across ten servers and one still melts. How partitioning by date, by hash and by celebrity post creates hot spots, and how to fix it.
 StreamingYard · · 4 min read
Prefer video? Watch the reel
1:00 · same idea, with sound
Prefer video? Watch the reel
1:00 · same idea, with sound
The setup
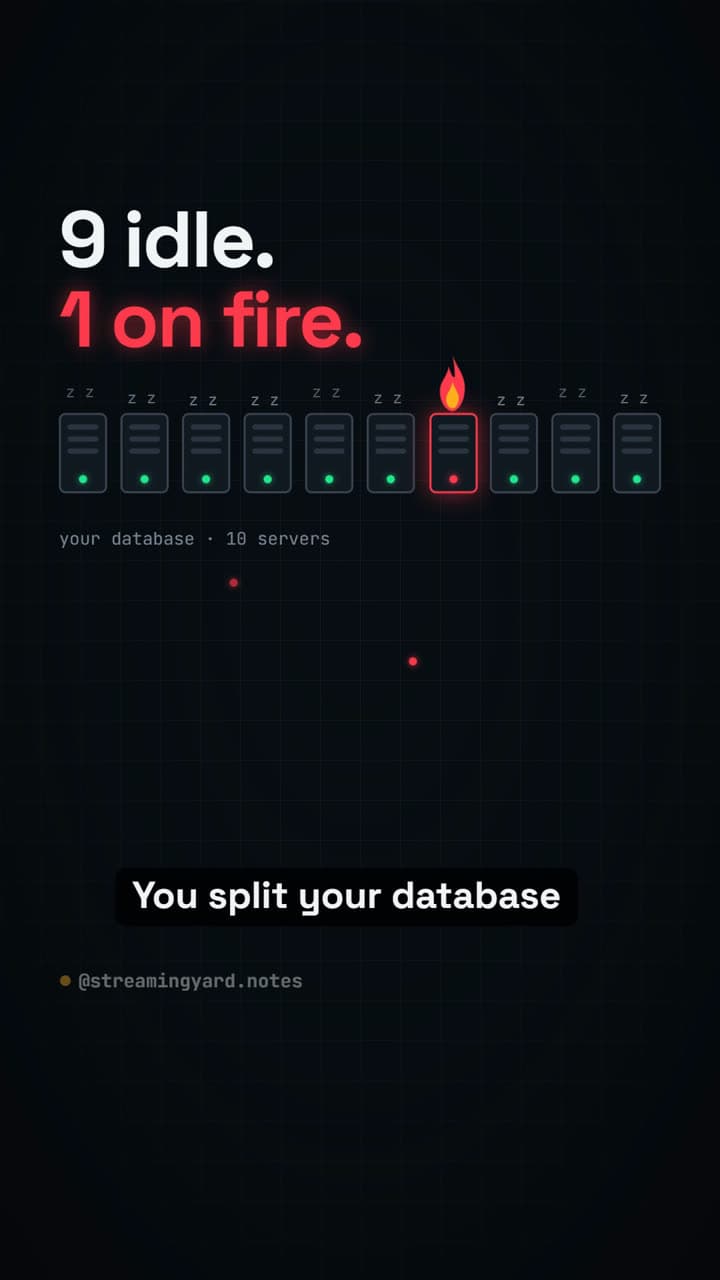
Say you run a photo app with a billion posts. That is too much data, and too much traffic, for one machine. So you do what every growing system eventually does: you partition it. You split the posts across ten servers (call them shards or partitions), and each one holds a slice of the data.
The whole point of partitioning is to spread load. If you split well, each of the ten servers handles roughly a tenth of the reads and writes, and you can keep adding servers as you grow. If you split badly, one server ends up with far more than its share. That server is a hot spot: nine machines sit mostly idle while one is pinned at 100% CPU and dragging your latency up for everyone.
The tricky part is that a hot spot is not caused by how much data a server holds. It is caused by how much traffic the keys on that server attract. Two servers can store exactly the same number of rows and still see wildly different load.
First try: split by date
The most natural way to split time-ordered data is by key range. Server one gets January, server two gets February, and so on. It looks tidy. Range queries are cheap too: “show me every post from March” goes to exactly one server.
Now think about where writes go. Every new post is written today. So every single write lands on whichever server owns the current month, while the other nine handle only reads of old posts. You bought ten servers and your write throughput is still limited to one.
This is the classic hot spot from key-range partitioning on a timestamp. The usual way out is to put something other than time first in the key, for example the user ID or the sensor name, and only then the timestamp. Writes from many users now spread across many ranges, and you can still ask for one user's posts in a time window by querying a single range.
-- hot: every new row has the largest key
key = created_at

-- spread: many writers, each with their own range
key = (user_id, created_at)Second try: hash the post ID
If you don't need range scans by time, you can partition by a hash of the key instead. Run each post ID through a hash function and use the result to pick a server. A good hash scatters even consecutive IDs uniformly, so new posts land evenly across all ten servers.
def shard_for(post_id: str, shards: int = 10) -> int:
    # Use a stable hash (not Python's per-process hash()).
    h = int.from_bytes(hashlib.md5(post_id.encode()).digest()[:8], "big")
    return h % shards
In production you rarely use plain modulo, because changing the number of shards would move almost every key. Systems like Cassandra and DynamoDB assign ranges of the hash space to partitions, so adding capacity only moves the keys in the ranges that get split.
Hashing has a cost. Adjacent keys are no longer adjacent on disk, so a query like “show me March” no longer maps to one server. It has to be sent to every server and the answers merged (a scatter-gather query), and the slowest server sets the latency. Many databases offer a compromise: hash the first part of a compound key to choose the partition, then keep rows sorted by the rest of the key inside it.
Then a celebrity posts
Hashing fixes uneven key distribution. It does nothing for one key that is simply very popular. A celebrity posts a photo and a million likes hit that one post in a few minutes. One post ID always hashes to one server, no matter how good your hash function is, so that server takes the whole storm.
Most databases can't fix this for you automatically; the application has to. The standard trick is key salting: append a random number to the hot key so its writes are spread over many keys, and therefore many servers.
# write: spread one hot key over 100 sub-keys
key = f"{post_id}#{random.randrange(100)}"
counter.incr(key)

# read: gather all 100 and combine
likes = sum(counter.get(f"{post_id}#{i}") for i in range(100))
Writes now fan out across a hundred keys. The price moves to reads, which must now fetch from all hundred and combine the results. You also need bookkeeping to know which keys are salted. So you don't do this for every key, only for the small number you know are hot.
What to take away
Partitioning only spreads load if your keys spread load. Before choosing a partition key, ask two questions: where will new writes land, and could one key ever get a big share of the traffic? Time-ordered keys answer the first badly; celebrity keys answer the second badly. Hashing fixes the first, and salting fixes the second, each at the cost of more expensive reads.
Source: Designing Data-Intensive Applications, chapter 6 (Partitioning).