How Twitter's timeline fan-out works
Twitter served 300,000 home-timeline requests a second. Why reading on demand melted, how fan-out on write fixed it, and the hybrid that handles celebrities.
 StreamingYard · · 2 min read
Prefer video? Watch the reel
0:52 · same idea, with sound
Prefer video? Watch the reel
0:52 · same idea, with sound
The shape of the load
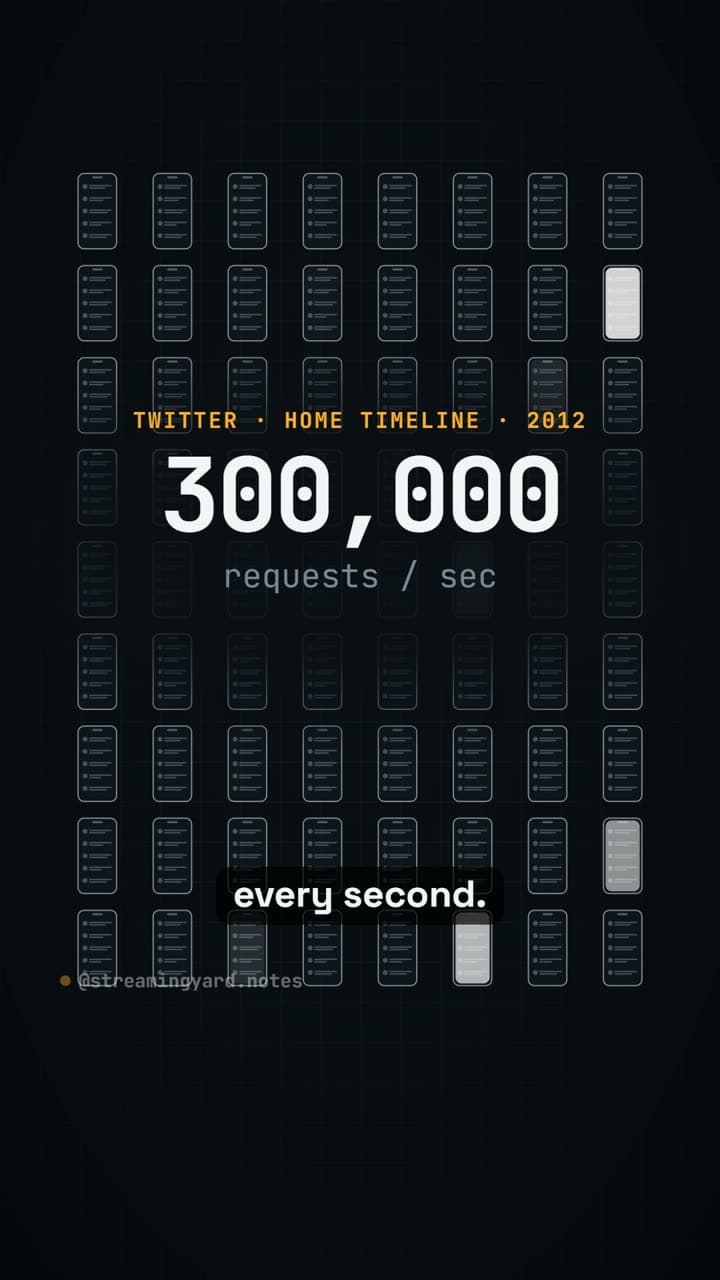
In 2012 Twitter handled around 300,000 home-timeline requests a second, while people posted about 4,600 tweets a second on average (around 12,000 at peak). Timelines were read roughly 65 times more often than tweets were written.
Posting a tweet is easy at that rate. The hard part is fan-out: each user follows many people and is followed by many people, and every timeline read has to bring together tweets from all the accounts that user follows. That ratio between reads and writes, and the number of followers per user, is what decides the design.
Version 1: build the timeline on read
The first approach is the one you would write in a database class. Tweets go into one global table. When you open the app, the database looks up everyone you follow, grabs their recent tweets and sorts them by time.
SELECT tweets.*, users.*
FROM tweets
JOIN users ON tweets.sender_id = users.id
JOIN follows ON follows.followee_id = users.id
WHERE follows.follower_id = :current_user
ORDER BY tweets.created_at DESC
LIMIT 50;
Writes are cheap: one insert per tweet. But every read is an expensive join across many users, and you run it 300,000 times a second. Twitter's systems struggled to keep up with that read load.
Version 2: fan out on write
So Twitter flipped it. Every user gets a pre-built home timeline, a cache that works like a mailbox. When someone tweets, the system looks up all their followers and inserts the new tweet into each follower's mailbox.
def post_tweet(author, tweet):
    save(tweet)
    for follower in followers_of(author):
        timeline_cache[follower].prepend(tweet.id)

def home_timeline(user):
    return timeline_cache[user][:50]  # already built: one cheap read
Opening the app is now a single cheap read. The work moved to write time, which makes sense when reads outnumber writes by two orders of magnitude. With an average of about 75 followers, 4,600 tweets a second become roughly 345,000 timeline-cache writes a second. That's a lot, but it is spread across many machines and done in the background.
The celebrity problem
The average hides the outliers. Followers are wildly uneven: most accounts have a handful, a few have tens of millions. When a celebrity with 30 million followers tweets, that one tweet becomes 30 million cache writes. Twitter aimed to deliver tweets to followers within about five seconds, and a single celebrity tweet could blow through that.
The hybrid
The final design mixes both approaches. Tweets from most users are still fanned out on write. Tweets from a small number of accounts with huge followings are not; they are fetched separately when you open your feed and merged into your pre-built timeline at read time.
def home_timeline(user):
    pushed = timeline_cache[user][:50]
    pulled = [recent_tweets(c) for c in followed_celebrities(user)]
    return merge_by_time(pushed, *pulled)[:50]
Each read does a little extra work, but only for the few celebrities you follow, and no single tweet can trigger millions of writes.
The lesson: measure the shape, not just the volume
“300,000 requests a second” doesn't tell you how to design the system. The ratio of reads to writes and the distribution of followers do. Before scaling anything, describe your load with the numbers that actually drive cost: read/write ratio, fan-out per write, and how skewed the distribution is. Then design for the bulk of users and add a special path for the outliers.
Source: Designing Data-Intensive Applications, chapter 1 (Describing load).
We put this to work in Live streaming app development and Video CDN & adaptive bitrate streaming.